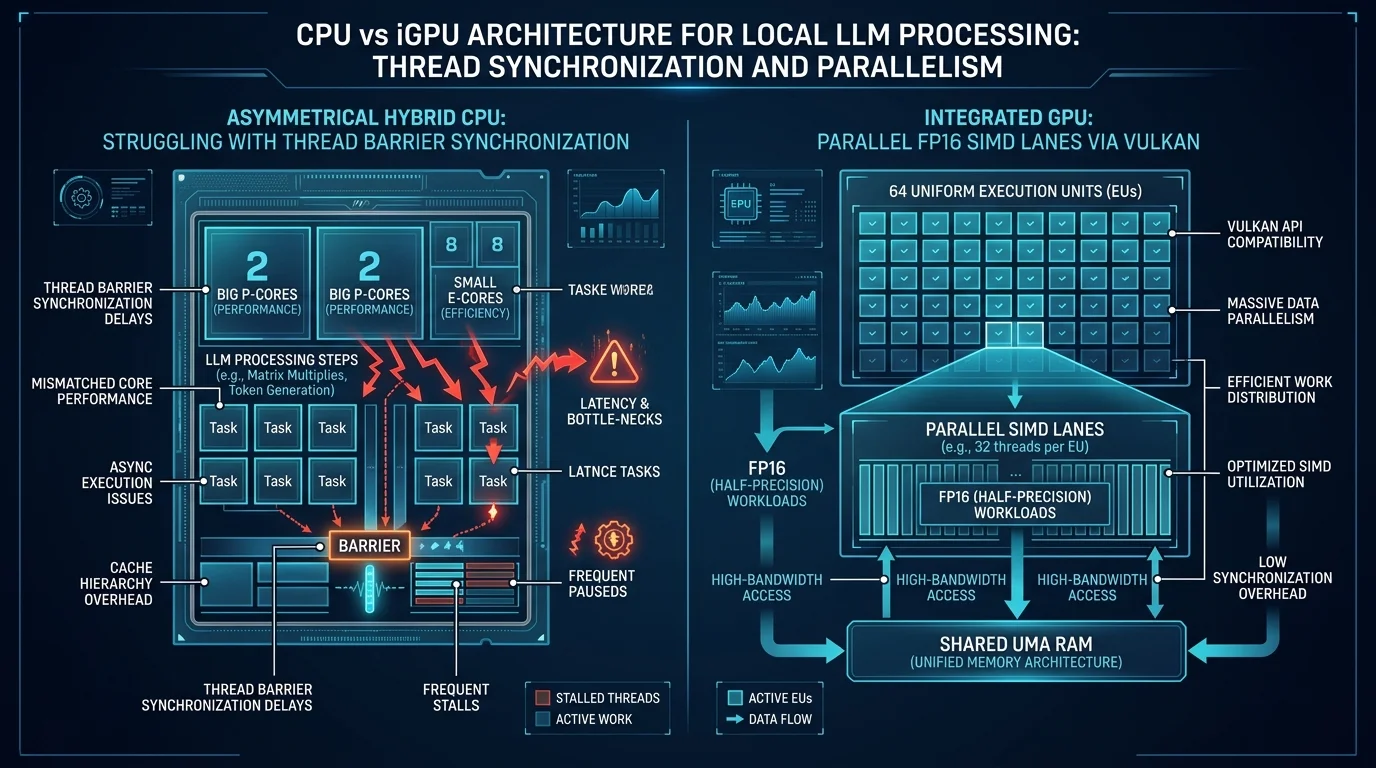
If you have spent five minutes lurking on Reddit, Hacker News, or local LLM Discord channels, you have heard the dogma: "If you do not have a discrete NVIDIA GPU, do not bother with GPU offloading. Integrated graphics have no VRAM, share your system RAM, and will just slow you down. Stick to CPU with AVX2." Even AI assistants will regurgitate this textbook wisdom with absolute confidence. They will cite memory bandwidth equations, point out your modest 64 Execution Units, and politely tell your Intel UHD graphics to go sit in the corner. There was only one problem: when we actually tested it on real hardware, the integrated GPU was noticeably and consistently faster than the CPU alone.
Benchmarking Ollama Over Tailscale & LAN: Squeezing Sub-Second Latency Out of the Grav AI Chatbot In Part III of this series, we built a 5-tier pipeline for grav-ai-chatbot, running local AI search on a 6-Watt Intel Celeron laptop. But once real traffic started hitting it from different dev...