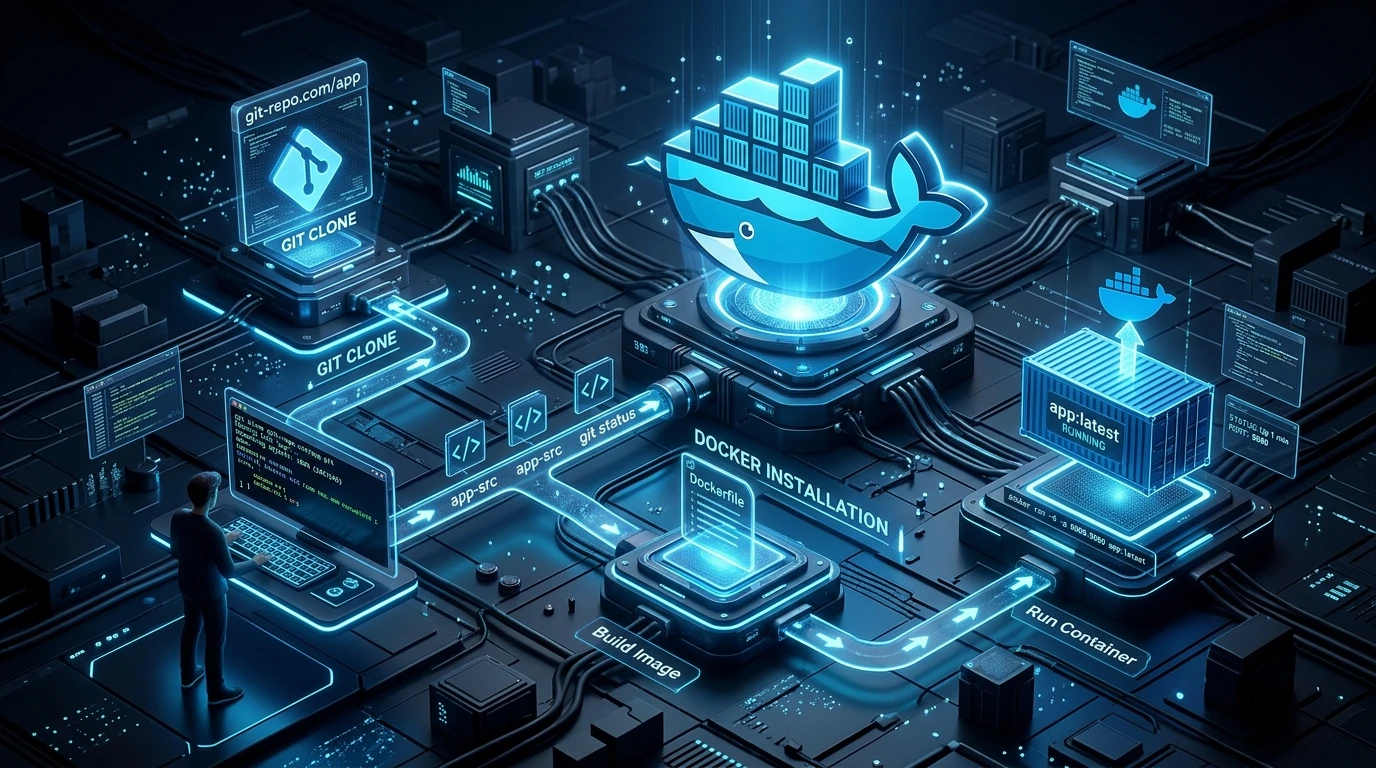
A step-by-step beginner-friendly guide to setting up and deploying Grav CMS using docker-lamp-grav on Linux VPS, macOS, and Windows environments.
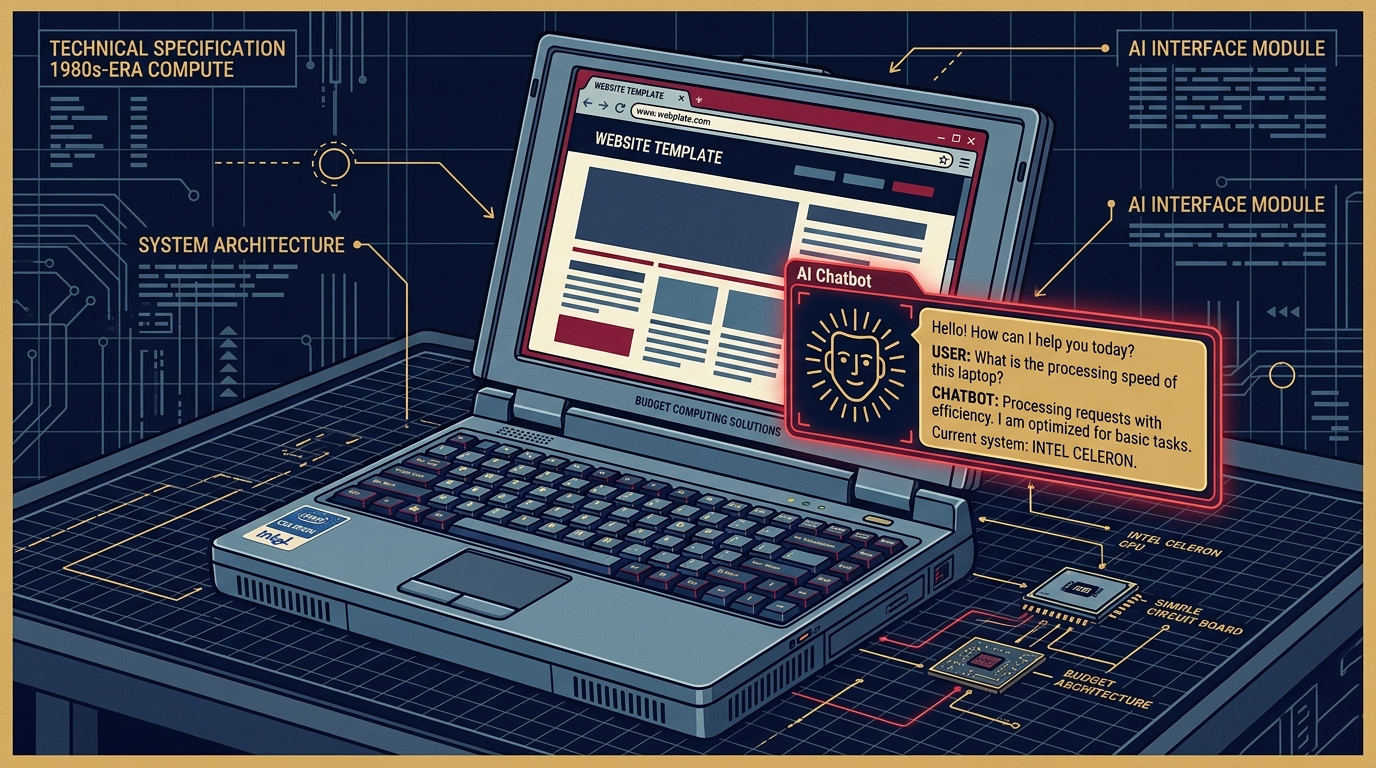
In Part IV of this series, we benchmarked local LAN and Tailscale mesh network latency for grav-ai-chatbot, proving that network transport was fast and reliable. But shortly after deploying reasoning models like qwen3.5:2b to production, users began reporting a perplexing bug: sending a sim...
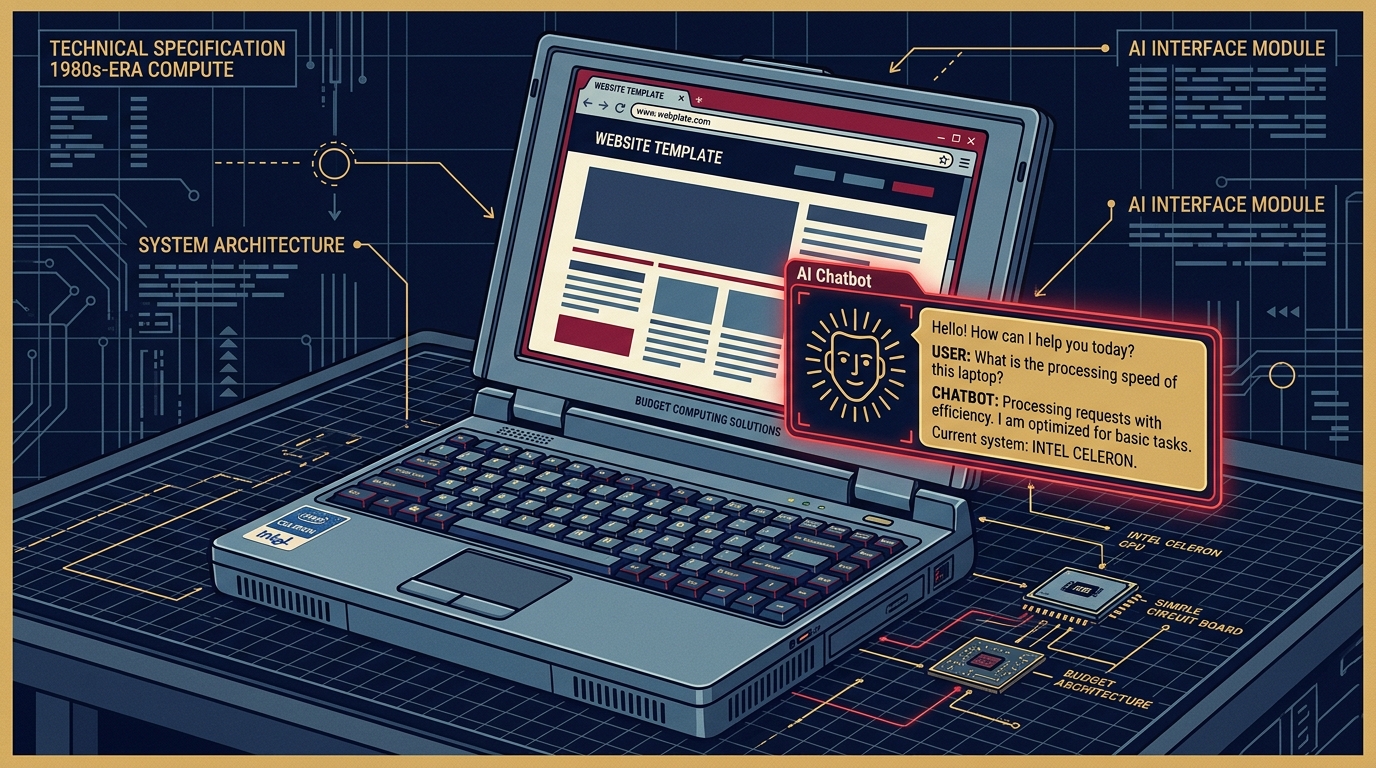
Benchmarking Ollama Over Tailscale & LAN: Squeezing Sub-Second Latency Out of the Grav AI Chatbot In Part III of this series, we built a 5-tier pipeline for grav-ai-chatbot, running local AI search on a 6-Watt Intel Celeron laptop. But once real traffic started hitting it from different dev...
Fast, Local, and 6-Watt Powered: Squeezing an AI Chatbot into Grav CMS In the previous article, Self-Hosting Local AI on a Celeron N4100 Laptop, I proved that a low-spec, 6-Watt Celeron laptop with 8 GB of RAM could comfortably run Ollama and serve lightweight models like Qwen2.5 (0.5B)....
An in-depth guide on designing lightweight, resilient Docker development environments for Grav CMS, PHP 8.3, Apache 2.4, and modern Linux server infrastructure.